Hi, I'm Manglesh
Turning research into production-grade AI that delivers measurable business impact.
About Me
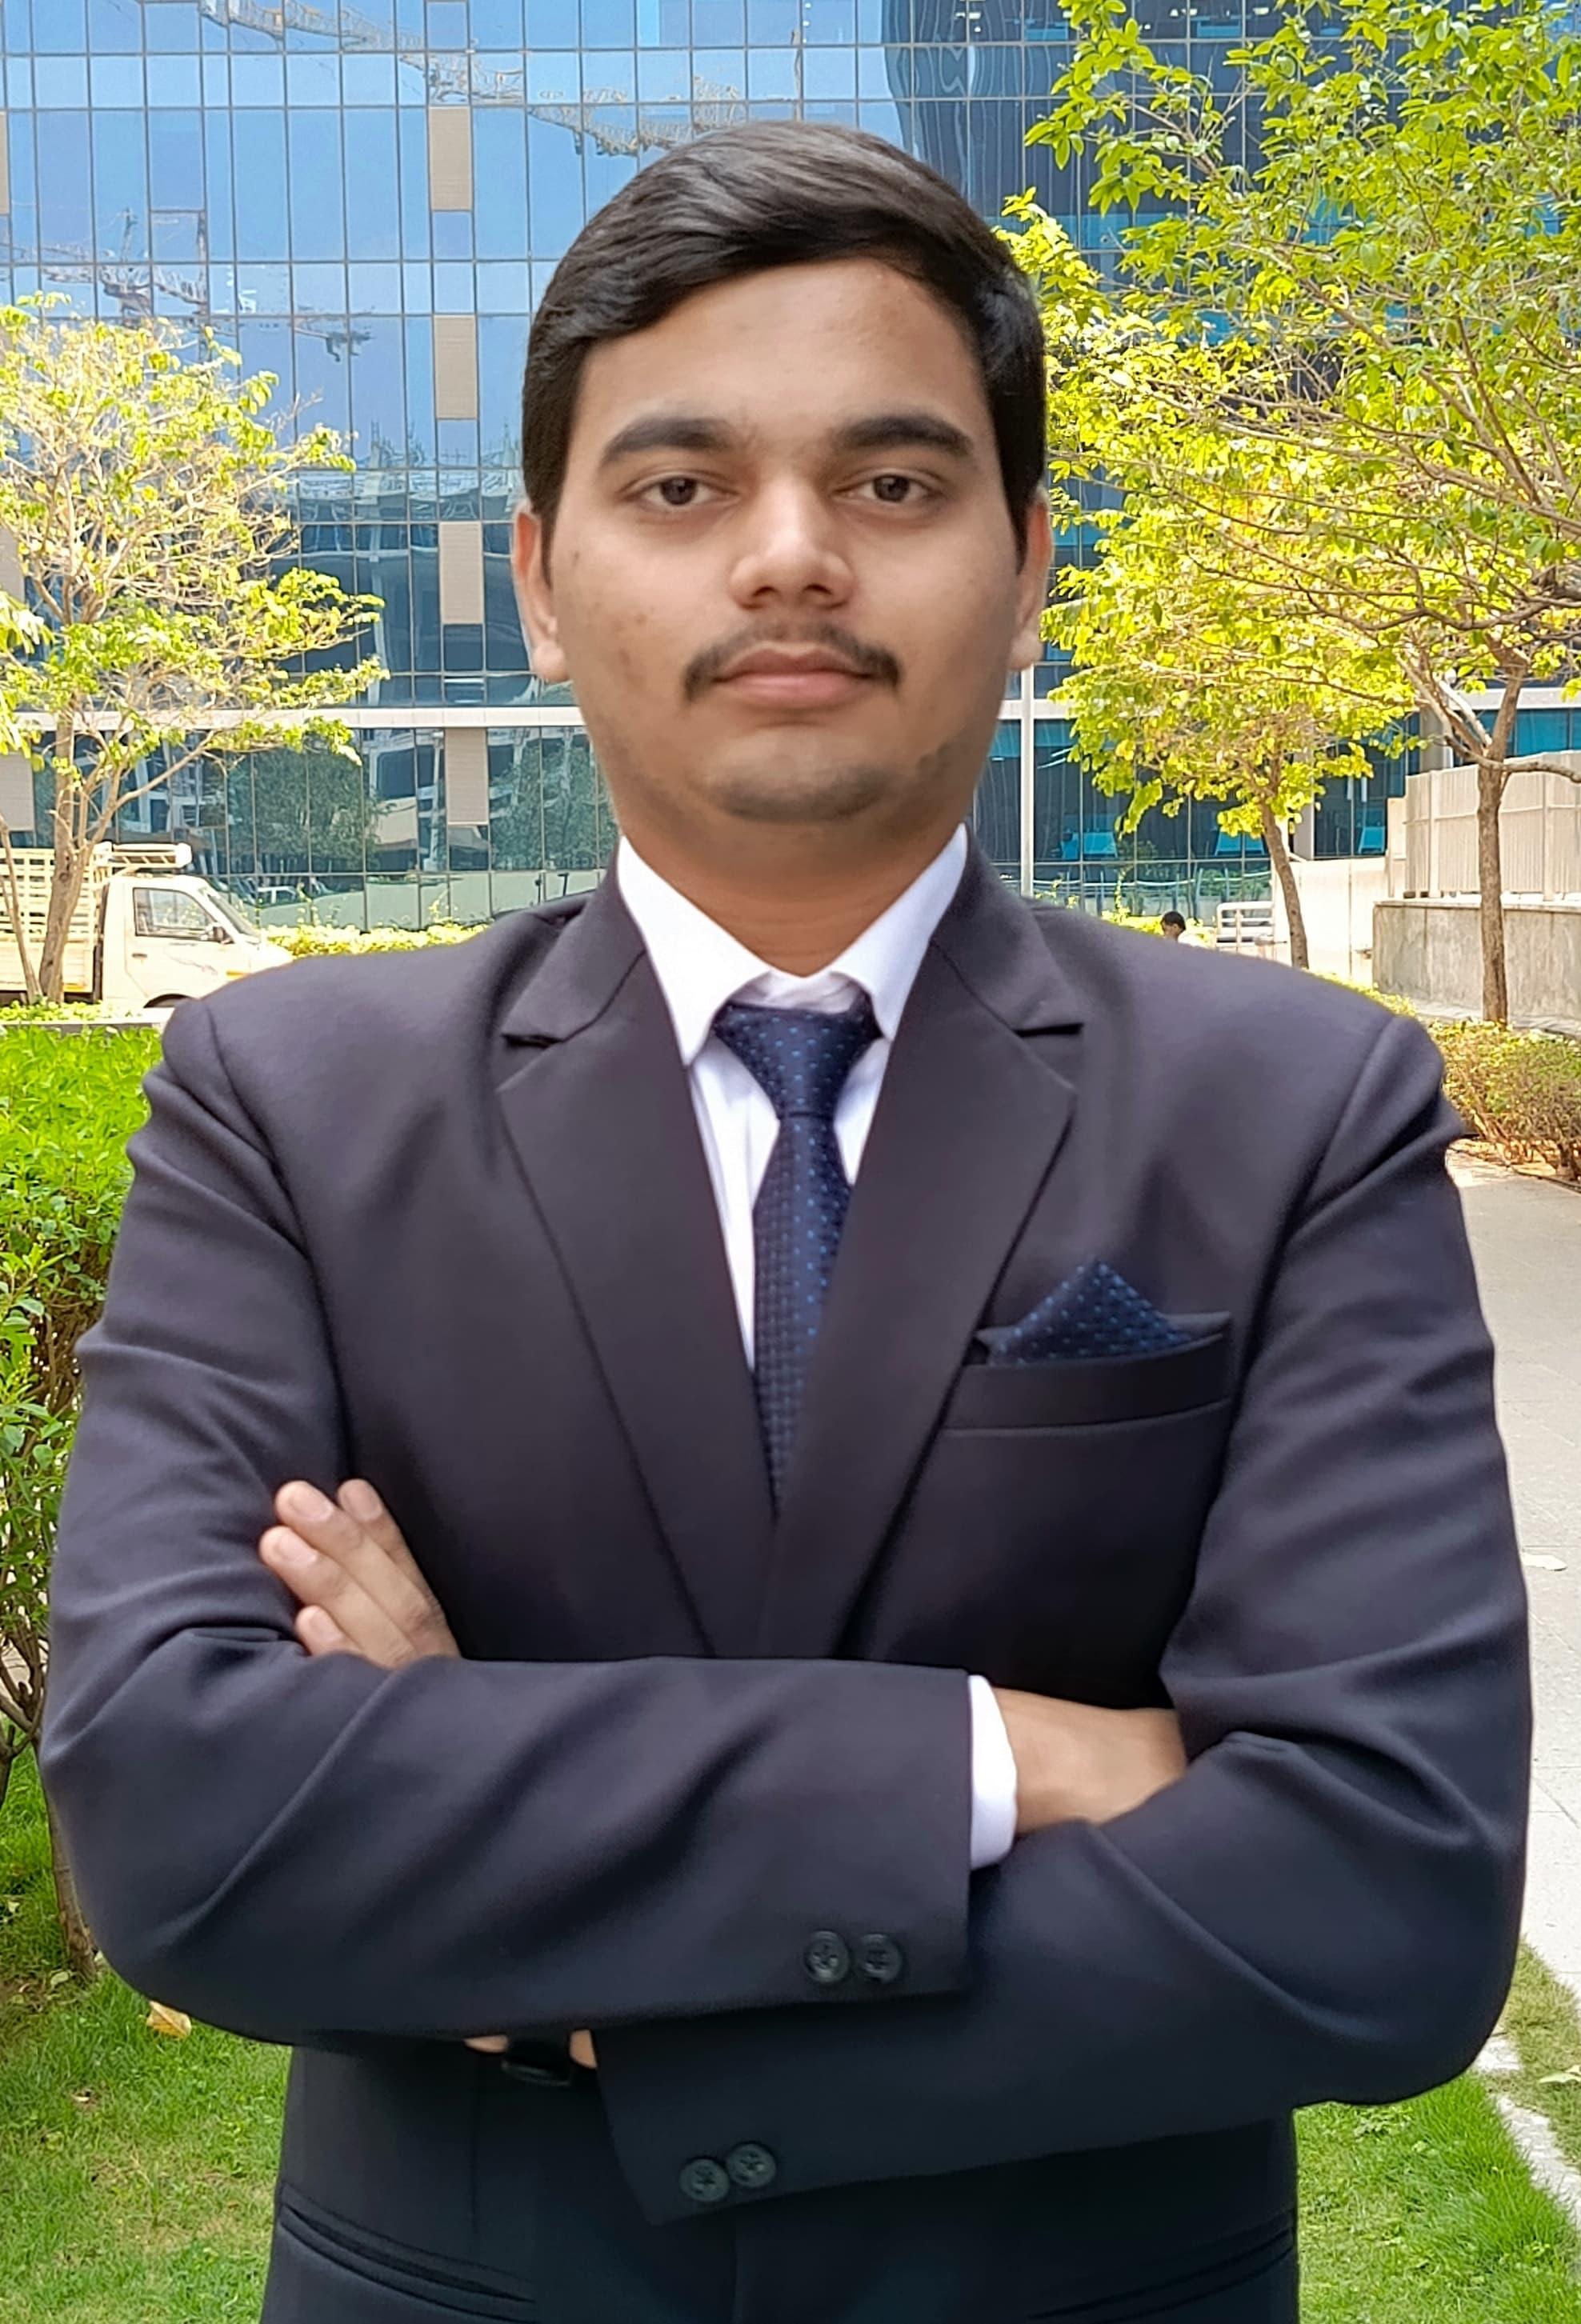
Most ML engineers stop at the notebook. I don't.
At Infineon Technologies, I built analytics pipelines processing 100K+ daily job records with PySpark, cutting analysis time from hours to minutes. At Apptware Solutions, I shipped NLP systems that automated resume screening and eliminated 80% of manual work.
I graduated from VIIT Pune with a 9.54 CGPA, published research on skin cancer detection at ICDECT 2024, and won 7+ national hackathons with total prize money exceeding ₹3.5 lakhs—including Novartis NEST (₹1.25L) and Tally CodeBrewers (₹75K).
I specialize in taking AI from prototype to production: NLP, deep learning, retrieval systems, and cloud deployment with measurable business impact.
7+
Hackathon Wins
3.5L+
Prize Money
9.54
CGPA
2
Publications
Achievements
7+
National Wins
₹3.5L+
Prize Money
9
Competitions
Hackathons & Competitions
NEST by Novartis
National Level - Novartis India
Built: AI-powered clinical trial matching system
Tally CodeBrewers 2024
National Level - Tally Solutions
Built: Intelligent document processing pipeline
MindSpark NeuroHack 2024
L&T sponsored
Built: Real-time anomaly detection system
PluginLive Hackathon 2024
PluginLive Technologies
Built: Automated candidate-job matching engine
CodeCraft 2025
Apptware Solutions
Built: Multi-modal AI assistant prototype
Viz-a-thon 2024
Wolters Kluwer sponsored
Built: Interactive legal analytics dashboard
GeekVishwa 2025
Built: Full-stack ML application
Technofea 2.0 2025
Built: End-to-end data pipeline
Amazon ML Summer School 2024
Competitive selection
Certifications & Programs
Data Analysis using Python
NPTEL
Rank in Top 1%AI-ML Virtual Internship
Google via Eduskills AICTE
Selective programAWS Data Engineering
Eduskills AICTE
Amazon ML Summer School
Amazon
Competitive admissionExperience
Apprentice
Infineon Technologies
- Architected and deployed an end-to-end analytics pipeline processing 100K+ daily LSF job records using PySpark on Zeppelin, implementing parallel processing to compute license runtime metrics across 10+ EDA tools, reducing analysis time from hours to minutes.
- Engineered ETL workflows with multi-threaded data processing and custom scheduling (daily/weekly) to transform raw license checkout events from Hadoop tables into curated datasets, enabling standardized runtime and queue contention reporting.
- Designed and published interactive Tableau dashboards consuming Hadoop-backed data sources, providing tool owners, project managers, and IT teams actionable insights into job distribution, resource contention, and performance trends.

Data Science Intern
Apptware Solutions
- Automated HRMS resume screening by building an NLP pipeline to match client JDs with internal candidate profiles, enabling instant identification of top experts and reducing manual efforts by 80%.
- Engineered a monocular depth-estimation solution using pre-trained depth-map models and OpenCV edge detection to calculate object dimensions from a single image without reference markers (error margin of +/-5cm).
- Developed a franchise-finder POC with a headless-browser agent (Browser Use) and proxy rotation to scrape and consolidate location data, integrating OpenAI API for enhanced extraction within 2-3 minutes.
- Contributed to open-source by fixing a Pydantic memory-config validation bug in the Browser Use module on GitHub, improving automation stability.
Featured Projects
Trial Scout
NLPClinical trial search in seconds, not weeks
Researchers spend weeks manually searching through 450K+ clinical trials to find relevant studies. Existing tools rely on keyword matching, missing semantically similar trials.
Built a semantic retrieval system using FAISS vector search with E5 Large Instruct embeddings (STS score 76.81). Designed domain-aligned embedding pipeline for medical terminology.
Reduced trial discovery time from weeks to under 3 seconds. Achieved 30% higher retrieval precision than keyword baselines. 10x cost reduction vs. proprietary alternatives.
Chronix
Full-Stack MLEnd-to-end AI platform for chronic disease prediction
Early detection of chronic diseases like diabetes and hypertension can significantly reduce healthcare costs, but existing screening tools are fragmented and single-purpose.
Deployed full-stack platform on GCP Cloud Run with real-time analytics via MongoDB sharding. Built ensemble ML models and an LLM-powered multilingual chatbot using LangChain with Knowledge Graph Augmentation.
95.6% accuracy on custom validation set of 12K patient records (vs. 89% logistic regression baseline). Sub-second chatbot response latency. Architected for horizontal scaling with load-tested capacity of 10K concurrent connections.
Handwritten Text Recognition
Computer VisionResearch-grade OCR with novel hybrid architecture
Existing OCR systems struggle with handwritten text due to style variation. Standard CNN approaches plateau around 90% accuracy on benchmarks like IAM.
Pioneered a CNN-BiLSTM-Transformer hybrid architecture combining ResNet feature extraction with Vision Transformer (ViT) attention and CTC decoding. Used self-supervised pre-training on unlabeled handwriting samples.
97.5% accuracy on IAM dataset (WER 0.1603, CER 0.0497) - surpassing previous approaches by 3.2%. Integrated NER and keyword extraction processing 100K+ POS tagging operations.
Technical Skills
Expert
Used daily in production work



Proficient
Shipped projects with these




Familiar
Working knowledge, used in projects


Published Research
An Analysis of the Performance of Binary and Multiclass Models for Early Diagnosis of Skin Cancer
ICDECT 2024 (International Conference)
My contribution: Designed experimental methodology, trained and benchmarked 5 CNN architectures, authored results and analysis sections
KrishiShakti: Decision Support System for Modern Farmers
Research Publication
My contribution: Led system architecture design, implemented ML prediction models for crop recommendation
Let's Connect
Open to AI/ML engineering roles, research collaborations, and interesting problems to solve.